
Like many people, when I'm on the go and need to do something, I reach for an LLM assistant. In my case, that's Claude. Anthropic, OpenAI, and Google all have a variety of connections to various services. But what happens when they don't have a connection to a service that you want?
For example, I've been dieting, which means I need to track my calories. I use MyFitnessPal for that. Tracking calories is laborious and difficult. Much of the difficulty comes from estimating the calories in a meal. What are the ingredients and components, and how much of each is there? If only there was a way to take a picture and have an intelligent system analyze the image and determine the calories. Oh wait, we do—LLM assistants!
Sadly, as far as I know, there's no connection to MyFitnessPal in any of the major LLM assistants. Wouldn't it be nice if my LLM could automatically log the estimated calories for me after analyzing the image?
This is where self-hosted MCP servers come in. Claude now allows you to add "custom integrations" to your account that it can use on the mobile app or on claude.ai. These custom integrations are just SSE-based MCP servers. If you have a server, you can run these integrations yourself.
There were a few complications for me:
-
There are several MyFitnessPal MCP servers, but they are stdio servers, which do not expose the HTTP endpoints that Claude's custom integrations require.
-
Although I have a server, it is behind a firewall, and I don't want to change that.
Fortunately, these problems aren't that difficult to solve. For the first problem, I used supergateway to expose the stdio MCP server as an SSE MCP server. For the second problem, I used ngrok to create a secure tunnel to my server without changing my firewall settings.
Setting up projects like this has never been easier. I asked Claude Code to
help, and it generated the docker-compose solution in about thirty minutes.
As is becoming more frequent, I found that the existing MyFitnessPal MCP servers were all lacking features I needed, such as the ability to see recent and favorite foods, delete log entries, and so on. So I forked them and vibe-coded the features I wanted. Forking the MCP servers and customizing them took a couple of hours spread over a few days of testing. Coding agents make this type of project easier than ever.
I'm still working out some edge cases with meal recognition and calorie estimation accuracy, but I've been really happy with the core functionality. Here's a screenshot of Claude estimating calories for some fries I photographed and logging them to MyFitnessPal automatically:
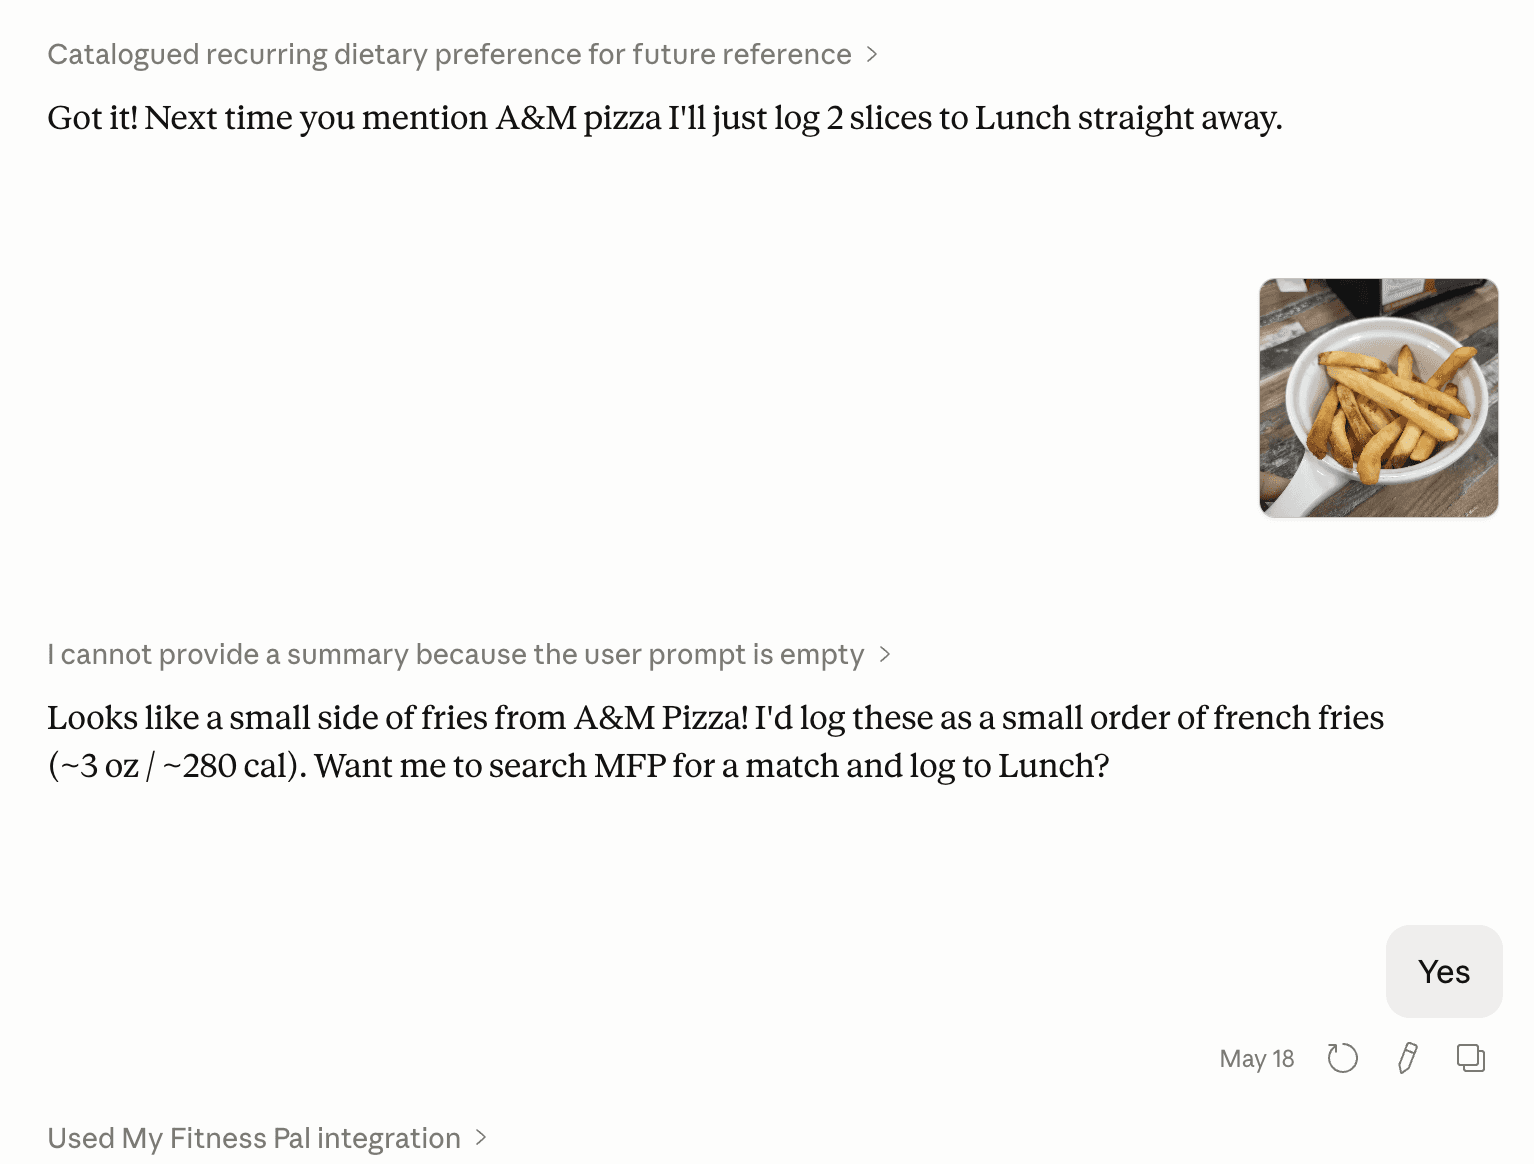
In claude.ai, I've created a project and been using memory to teach Claude about my diet, which is fortunately quite repetitive.
Check out the docker-compose setup and MyFitnessPal MCP server fork on GitHub. The MyFitnessPal MCP server is included as a submodule.
New open LLMs are released constantly and keep improving. Gemma 4 was recently claimed to be groundbreaking, but when I tried the quantized version for coding agents like opencode, it was completely unusable—it gets stuck in output loops or unable to call tools with correct syntax. This is the norm, not an exception. Most quantized open LLMs I try for agentic AI simply don't work. Finding a setup that does requires trial and error across model, quantization, and dozens of settings.
I just want a command I can run to get a working LLM for my GPU. No hours of experimentation. No guessing at combinations. Just a proven setup. I couldn't find one, so I built auto-bench.
auto-bench
Auto-bench is a tool that allows you to define experiments, automatically run LLM inference servers with the proper settings, and execute a set of benchmarks against them. Rather than reinventing the wheel, I'm currently using Harbor Framework to run the tests. Auto-bench has first-class support for quantized models. This is important, because most existing benchmarks and leaderboards don't consider quantization, even though that is how many people run models.
My project is in its earliest stages, but I have at least one experiment to share: testing various quantizations of the Qwen3.5-2B model on a single problem instance from SWE-bench Verified (swe-bench/sympy__sympy-22914). I deliberately selected an easy instance to see if quantized models can perform basic tool calls to solve an easy problem.
Here is how this experiment is configured in auto-bench:
# Benchmark 22 quants of Qwen3.5-2B on a single SWE-bench instance
# Usage: auto-bench run configs/qwen-2b-quant-sweep.yaml

name: qwen-2b-quant-sweep
backend_type: llamacpp
dataset: SWE-bench/SWE-bench_Verified

instance_ids:
  - swe-bench/sympy__sympy-22914

model:
  name: Qwen3.5-2B
  source: huggingface
  repo_id: unsloth/Qwen3.5-2B-GGUF
  sweep:
    - label: BF16
      filename: Qwen3.5-2B-BF16.gguf
    - label: Q3_K_S
      filename: Qwen3.5-2B-Q3_K_S.gguf
    - label: Q5_K_M
      filename: Qwen3.5-2B-Q5_K_M.gguf
    - label: Q5_K_S
      filename: Qwen3.5-2B-Q5_K_S.gguf
    - label: Q6_K
      filename: Qwen3.5-2B-Q6_K.gguf
    # ... 17 more quantizations

sampling:
  temperature: 0.7
  top_p: 0.8
  top_k: 20
  min_p: 0.0
  presence_penalty: 1.5
  repetition_penalty: 1.0
agent:
  agent: openhands
  env: docker
  attempts: 4
  limit: 1
  setup_multiplier: 10.0

evaluation:
  run_evaluation: true
Part of my goal is to include all information needed to actually run the models properly. For example, the sampling section includes the sampling parameters that are recommended by Qwen for best performance, and these types of details can make a huge effect! My vision is to eventually have a leaderboard that will provide you with a llama.cpp command-line to run the model with the proper settings, and then you can just copy and paste that command to get a working LLM for your coding agent.
Results
Before diving into the data, here's what the columns mean:
- Resolved: Number of problem instances successfully resolved by the agent
- Total: Total number of attempts (8 in this case)
- % Resolved: Resolution rate as a percentage
- PPL (Perplexity): Measures the model's confidence in its predictions. Lower is generally better, though surprisingly this doesn't always correlate with task success
- KL: Kullback-Leibler divergence—how much the quantized model's output distribution diverges from the original model's. Lower is better, but as we'll see, it's not a strong predictor of task performance
- Runtime: Total time to run all attempts
- Exceptions: Types of errors encountered (e.g., timeouts, exit code errors)
| Quant | Resolved | % | PPL | KL | Runtime | Exceptions |
|---|---|---|---|---|---|---|
| BF16 | 0/8 | 0% | 13.38 | — | 3m 37s | — |
| IQ4_NL | 1/8 | 12.5% | 13.67 | 0.0309 | 3m 53s | — |
| IQ4_XS | 0/8 | 0% | 13.68 | 0.0318 | 51m 53s | Timeout, ExitCode |
| Q3_K_M | 2/8 | 25% | 14.33 | 0.0774 | 51m 48s | Timeout |
| Q3_K_S | 5/8 | 62.5% | 15.08 | 0.1334 | 51m 39s | Timeout |
| Q4_0 | 4/8 | 50% | 13.91 | 0.0454 | 19m 5s | — |
| Q4_1 | 3/8 | 37.5% | 13.68 | 0.0273 | 11m 14s | — |
| Q4_K_M | 1/8 | 12.5% | 13.79 | 0.0230 | 4m 8s | ExitCode |
| Q4_K_S | 2/8 | 25% | 13.78 | 0.0274 | 4m 43s | — |
| Q5_K_M | 8/8 | 100% | 13.46 | 0.0082 | 51m 48s | Timeout |
| Q5_K_S | 6/8 | 75% | 13.49 | 0.0100 | 8m 53s | — |
| Q6_K | 7/8 | 87.5% | 13.48 | 0.0035 | 51m 54s | Timeout |
| Q8_0 | 4/8 | 50% | 13.39 | 0.0012 | 51m 49s | Timeout |
| UD-IQ2_M | 0/8 | 0% | 17.61 | 0.2677 | 51m 56s | Timeout(5) |
| UD-IQ2_XXS | 0/8 | 0% | 27.11 | 0.7018 | 51m 58s | Timeout(6), ExitCode |
| UD-IQ3_XXS | 0/8 | 0% | 15.31 | 0.1549 | 51m 49s | Timeout |
| UD-Q2_K_XL | 0/8 | 0% | 17.15 | 0.2388 | 51m 49s | Timeout(2) |
| UD-Q3_K_XL | 6/8 | 75% | 13.94 | 0.0520 | 51m 56s | Timeout(2) |
| UD-Q4_K_XL | 6/8 | 75% | 13.60 | 0.0164 | 7m 40s | — |
| UD-Q5_K_XL | 8/8 | 100% | 13.51 | 0.0077 | 18m 2s | — |
| UD-Q6_K_XL | 3/8 | 37.5% | 13.48 | 0.0020 | 6m 51s | — |
| UD-Q8_K_XL | 3/8 | 37.5% | 13.37 | 0.0011 | 5m 49s | — |
| vllm | 1/8 | 12.5% | — | — | 6m 32s | — |
The Base Model Is Broken
The most striking finding is that the unquantized base model (shown as vllm in the results) achieves only 12.5% resolution—worse than most quantized versions. BF16, which is nearly the original model without quantization, also consistently fails at 0%. This suggests the base model is fundamentally broken for this coding task, but quantization somehow fixes it.
Many medium-sized quantizations (Q5_K_M, UD-Q5_K_XL, Q6_K) achieve 100%, 100%, and 87.5% resolution respectively. Yet larger quantizations like Q8_0 fail again at 50%. This isn't about bigger being better—it's about finding the quantization that repairs the base model's broken reasoning.
KL Divergence Doesn't Predict Success
The KL (Kullback-Leibler) divergence column measures how much a quantized model's output distribution diverges from the original. If the base model is broken for this task, then staying close to the original (low divergence) just means inheriting the same brokenness. That could explain why there's no strong correlation between divergence and success.
Q5_K_M achieves 100% resolution with low divergence (0.0082)—but so does UD-Q5_K_XL with similar low divergence. Meanwhile, BF16 (essentially 0 divergence, nearly the original) fails completely at 0%. Some high-divergence models like UD-IQ2_XXS fail too, but others like Q3_K_S achieve 62.5% with divergence of 0.1334.
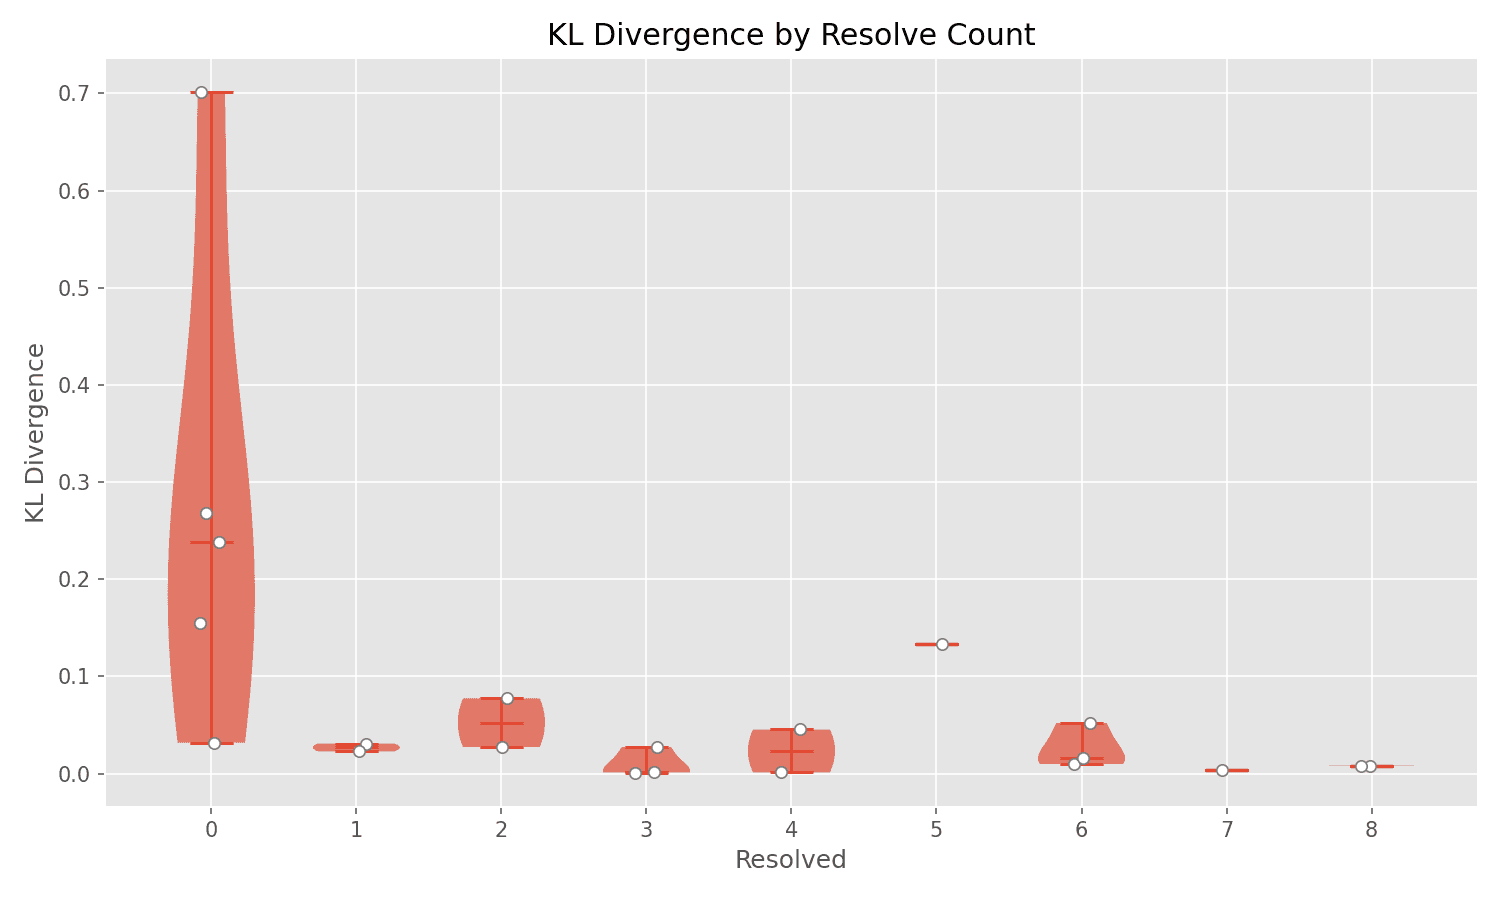
The plot tells the story: failing models (0 resolved) scatter across the entire divergence range—some very close to the original, some far away. If you stayed loyal to a broken base model, you'd fail. If you accidentally diverged in the right way, you'd succeed. KL divergence alone can't tell you which happened.
Multiple Failure Modes
There are two distinct failure modes visible in the results.
Failure Mode 1: Infinite Loops (AgentTimeoutError)
Many quantizations exhibit infinite looping behavior, where the agent gets stuck generating the same outputs repeatedly and eventually hits the timeout limit. Models like UD-IQ2_M, UD-IQ2_XXS, IQ4_XS, and IQ3_XXS show multiple AgentTimeoutError instances. Interestingly, this failure mode appears to correlate strongly with extremely aggressive quantization (e.g., IQ2 variants with very high KL divergence > 0.26).
Failure Mode 2: Silent Failure
The second failure mode is when the agent runs to completion without timing out, but simply fails to correctly solve the problem. Models like BF16, UD-IQ2_XXS, and UD-IQ3_XXS never produce output loops, but they still achieve 0% resolution. This suggests that the quantization has degraded the model's reasoning ability below a critical threshold where it can't effectively reason about code, even if it's still syntactically generating valid tool calls.
Conclusion: The Base Model Is Broken, Quantization Fixes It
The core finding is that the unquantized base model (12.5% resolution) and near-original BF16 (0% resolution) both fail for this coding task. Yet specific quantizations like Q5_K_M and UD-Q5_K_XL achieve 100%. Quantization isn't degrading a working model—it's repairing a broken one.
Notice in the visualization: models that fail (0 resolved) scatter across the entire KL divergence range, from very close to the original all the way to extremely divergent. Models that succeed tend to cluster at low divergence. But the scatter on the left side proves you can't predict failure from divergence—some quantizations stay very close to the original yet still fail.
The lesson is that model quality for coding agents is challenging to predict. This is why auto-bench exists—to empirically measure what actually works for your specific use case.
Open Questions and Limitations
This experiment demonstrates an interesting phenomenon, but it's based on a single problem instance from a single model family. The findings should be interpreted with appropriate caution:
- Generalization to other models: Do these patterns hold for Llama, Mistral, or other model families? The behaviors might be Qwen-specific.
- Generalization to other instances: I deliberately chose an easy instance to see if quantized models could work at all. Would the patterns hold on harder instances? SWE-bench Verified spans easy to extremely difficult problems.
- Generalization to other tasks: Would we see similar results on SWE-bench instances beyond Verified, or on other benchmarks like HumanEval or MBPP?
- Sampling parameter sensitivity: How much of the improvement from quantized models comes from properly-tuned sampling parameters? A controlled ablation would be valuable.
I'm actively running experiments to answer these questions! The auto-bench framework is designed to scale to hundreds of model/quantization combinations and thousands of problem instances. Stay tuned for results on larger model families, more problem instances, and more task types.
I'm happy to announce that my student Luke Dramko's paper "Idioms: A Simple and Effective Framework for Turbo-Charging Local Neural Decompilation with Well-Defined Types" has been accepted to NDSS 2026! Put simply, the paper shows that neural decompilers benefit greatly from explicitly predicting and recovering user-defined types (structs, unions, etc.) referenced in decompiled code.
Paper & Code
- Paper: https://edmcman.github.io/papers/ndss26.pdf
- Code & models: https://github.com/squareslab/idioms
The paper has a great motivating example that I'll borrow here. The example starts with a C function that uses a struct type:
struct hash {
  int hash_size;
  int item_cnt;
  struct gap_array *data;
  int (*hash_make_key)(void *item);
  int (*cmp_item)(void *item1, void *item2);
};
struct gap_array {
  int len;
  void **array;
};

int hash_find_index(struct hash *h, void *item) {
    void *cnx;
    int index = hash_make_key(h, item);
    int cnt = 0;
    cnx = gap_get(h->data, index);
    while (cnx != NULL) {
        if (cnt++ > h->hash_size) return -1;
        if (!h->cmp_item(cnx, item)) break;
        index = hash_next_index(h, index);
        cnx = gap_get(h->data, index);
    }
    if (cnx == NULL) return -1;
    return index;
}
If you've read this blog, it will probably not surprise you that even state-of-the-art decompilers like Hex-Rays struggle to recover this code in a human-readable form. Here is the output from Hex-Rays:
__int64 __fastcall func4(__int64 a1, __int64 a2) {
  int v2;          // eax
  __int64 result;  // rax
  int v4;          // [rsp+10h] [rbp-10h]
  unsigned int v5; // [rsp+14h] [rbp-Ch]
  __int64 i;       // [rsp+18h] [rbp-8h]
  v5 = func2(a1, a2);
  v4 = 0;
  for (i = func1(*(_QWORD *)(a1 + 8), v5); i;
       i = func1(*(_QWORD *)(a1 + 8), v5)) {
    v2 = v4++;
    if (v2 > *(_DWORD *)a1) return 0xFFFFFFFFLL;
    if (!(*(unsigned int(__fastcall **)(__int64, __int64))(a1 + 24))(i, a2))
      break;
    v5 = func3((_DWORD *)a1, v5);
  }
  if (i)
    result = v5;
  else
    result = 0xFFFFFFFFLL;
  return result;
}
There are a lot of problems with this output, but the most serious is that the
information about the hash struct has been completely lost.
A very exciting line of decompilation research is neural decompilation, which leverages neural models to either (1) directly decompile code, or (2) improve the decompiled code from traditional (non-neural) decompilers. I am personally extremely excited about the latter approach, which uses neural models to post-process the output of traditional decompilers such as Hex-Rays. Traditional decompilers have been studied for decades, so why not leverage their strengths while using neural models to fix their weaknesses? One popular example is the LLM4Decompile models. Here is an example of LLM4Decompile's output for this function:
int FUN_00100155(struct FUN_0009ff84 *VAR_0,void *VAR_1){
  int VAR_2;
  int VAR_3;
  void *VAR_4;
  VAR_2 = FUN_0009ff86(VAR_0, VAR_1);
  VAR_3 = 0;
  VAR_4 = FUN_0009ff88(VAR_0->VAR_5, VAR_2);
  while (VAR_4) {
    if (VAR_0->VAR_6 < VAR_3) { return -1; }
    if (!VAR_0->VAR_7(VAR_4, VAR_1)) { break; }
    VAR_2 = FUN_0009ff89(VAR_0, VAR_2);
    VAR_4 = FUN_0009ff88(VAR_0->VAR_5, VAR_2);
    VAR_3++;
  }
  if (VAR_4) { return VAR_2; }
  return -1;
}
Unlike Hex-Rays, LLM4Decompile correctly identifies that the function's
arguments are pointers and that the first argument is a pointer to a struct. But
what is struct FUN_0009ff84 and what are its fields, VAR_5, VAR_6, and
VAR_7? And perhaps most importantly for reverse engineers, what offsets are
those fields at? This information is crucial for understanding the code, but
it has been omitted by the model.
One of Idioms' main contributions is to modify the training process of neural models so that they produce well-defined types such as structs with named fields. Unsurprisingly, this makes decompiled code much easier to understand. Here is the output of Idioms on this function:
struct hash_t {
  int size;
  int count;
  struct hash_table_t *table;
  int (*hash)(void *key);
  int (*cmp)(void *key1, void *key2);
};
struct hash_table_t {
  int size;
  void **items;
};
int hash_find(struct hash_t *hash, void *key) {
  int index = hash_index(hash, key);
  int i = 0;
  void *item = hash_get(hash->table, index);
  while (item != ((void *)0)) {
    if (i++ > hash->size) { return -1; }
    if (hash->cmp(item, key) == 0) { break; }
    index = hash_next(hash, index);
    item = hash_get(hash->table, index);
  }
  return (item == ((void *)0)) ? -1 : index;
}
An Unexpected Advantage of Joint Predictions
Perhaps surprisingly, in addition to improving the readability of the code, jointly predicting both code and types also significantly improves the accuracy of the decompiled code!
Across multiple models and evaluation metrics, Idioms consistently outperforms prior neural decompilers:
- On ExeBench: Idioms achieves 54.4% test-pass accuracy (vs. 46.3% for LLM4Decompile and 37.5% for Nova).
- On RealType: A dataset we introduce that contains substantially more and more realistic user-defined types (UDTs); Idioms improves correctness metrics by 95–205% over prior work.
- Context helps: Adding neighboring-function context improves UDT recovery—up to 63% improvement in structural accuracy—with little downside for larger models.
Beyond Decompilation
Surprisingly (to me), Idioms also outperforms standalone type recovery tools such as Retypd, BinSub, TRex, and TypeForge, by at least 73%. This suggests that generative, context-aware approaches may be well suited to resolving the inherent ambiguity of type recovery than prior approaches, even though this was not the original motivation of Idioms.
(Apologies in advance, this is probably going to be rambling.)
I spend a lot of time looking at various research artifacts. Yesterday, I was looking at several verification artifacts, and I was struck by how much impact small details like a Docker container can have. One of the projects I was using is STOKE. STOKE is a cool project, but the salient detail for this post is that it is an abandoned research project. The last commit was in December 2020. This is very common: Ph.D. student creates a project, maintains project, graduates, and then no longer maintains project. Despite that, STOKE has a Docker container, which makes using the project trivial.
In contrast, I was also attempting to run Psyche-C this week. Like STOKE, there's a fair bit of bitrot on the branch that contains the type-inference component. Unlike STOKE, Psyche-C does not have a Docker container. Part of this branch uses Haskell lts-5.1, which is from 2016! Trying to get this running was a nightmare, since modern versions of stack, GHC and cabal could not cope with such an old environment. I was eventually able to get it running by creating an Ubuntu focal docker image but it took me an entire day. I also created a HuggingFace space for it.
I have said it before, but I just love HuggingFace spaces for hosting research artifacts. It makes it almost effortless for others to try out your research. I wish more researchers would use them.
I think that the decompilation and reverse engineering research community could also significantly benefit from using HuggingFace spaces and generally making artifacts easier to use. I say this because there are many subtle details about reverse engineering research artifacts that can make them less usable in practice.
For example, I was recently reading DecompileBench, which is a good paper about benchmarking decompilers. In particular, they have a very clever method for testing whether a decompiled function is semantically equivalent to the original source code. In short, they compile the decompiled function in isolation and splice it into the original program, and do some testing to see if it behaves the same way. I've been thinking about this topic a lot recently, since I have been talking with some of my students about it. The problem is that if the binary is stripped, the decompiler can't refer to symbols by their original name, and thus the decompiled code can't reliably be linked back into the original program. (Ryan pointed out on Bluesky that this is possible in some cases.) DecompileBench ignores this problem and decompiled unstripped binaries. This is a problem, because decompilers are usually used on stripped binaries, and they generally perform significantly worse on them.
My goal is not to criticize DecompileBench; I think it's a nice paper. My point is that there are many subtle details like this that can make research artifacts less useful in practice. I've had my own share. As one example, the DIRT dataset was stripped using the wrong command, so that function names were still present in the binary, which is unrealistic. Fortunately, it turned out (surprisingly) that this did not significantly affect the results in that paper, but it could have.
I think part of the problem with these two examples is that it's hard to get close to the actual use case with these projects. In decompilation, the real use case is decompiling stripped binaries in the wild. But it's hard to run DIRTY on a new binary to see how well it works. I have found this to be a common problem in machine learning-based research. The straight-forward approach is to start with a dataset for which you have ground truth, and then train and test on that dataset. This often leads to preprocessing code that expects to have the ground truth information available. This is problematic when you want to perform inference on a new example when you don't have ground truth information, e.g., the primary use case of these technologies!
My overall message is that docker containers and HuggingFace spaces are great ways to make research artifacts easier to use. This is important in general, but it's also important to be able to get as close to the real use case as possible. If, for example, your technique only works for unstripped binaries and you forget to mention this in your paper, a docker container or space is going to make that very apparent.
I have a pretty hot take: the top-tier conferences should mandate that research artifacts be easy to use, e.g., via docker containers or HuggingFace spaces, on new examples, and that these artifacts should be considered as part of the submission. Having a separate, optional artifact evaluation process simply doesn't work. (The incentive for going through the artifact evaluation is a badge, which is essentially a sticker for grown-ups!) But if reviewers can actually try out the artifact on new examples, they can see how well it works in practice. This would significantly improve the quality of research artifacts in our community.
My colleague Cory Cohen recently asked me to take a look at some surprising behavior in Ghidra's decompiler. He had a decompiled function that looked like this:
/* WARNING: Globals starting with '_' overlap smaller symbols at the same address */
void HI_MPI_SVP_NNIE_LoadModel(model *model_buf,uint *out_buf,ulong param3)
{
uint64_t uVar1;
byte bVar2;
byte bVar3;
ushort uVar4;
ushort uVar5;
short sVar6;
long lVar7;
uint32_t error;
int iVar8;
int flag;
ulong uVar9;
ulong neg_counter;
byte *pbVar10;
byte *pbVar11;
uint uVar12;
ulong uVar13;
uint64_t vir_addr;
long lVar14;
uint uVar15;
ulong uVar16;
byte *local_e8;
uint local_d8;
uint local_d4;
header header_buf;
ulong counter;
uint size;
lVar7 = ___stack_chk_guard;
_header_buf = 0;
error = svp_nnie_check_loadmodel_param_user(model_buf,(long)out_buf);
if (error == 0) {
size = (uint)model_buf->size;
if (size < 0xc1) {
error = 0xa0338003;
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x): model_buf->size(%u) must be greater than %u!\n "
,"hi_mpi_svp_nnie_load_model",0x345,0xa0338003,(ulong)size,0xc0);
}
else {
vir_addr = model_buf->vir_addr;
memcpy_s(&header_buf,0xc0,vir_addr);
if (false) { fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x): model_buf->size(%d) is less than %d!\n",
"svp_nnie_parse_model_header",0x1b2,0xa0338003);
}
else {
if (false) {
flag = -1;
}
else {
neg_counter = 0;
pbVar10 = (byte *)(vir_addr + 4);
do {
pbVar11 = pbVar10 + 1;
size = *(uint *)(&DAT_00105d70 + ((neg_counter ^ *pbVar10) & 0xff) * 4) ^
(uint)neg_counter >> 8;
neg_counter = (ulong)size;
pbVar10 = pbVar11;
} while ((byte *)(vir_addr + 0x100000000) != pbVar11);
flag = ~size;
}
if (header_buf.unk1 == flag) {
memset_s(out_buf,0x36a8,0);
if (true) {
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x):model_version(%u) of input model should b e %d!\n"
,"svp_nnie_parse_model_header",0x1c3,0xa0338003,0,0xb);
}
else if (true) {
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x):arch_version(%u) of input model should be %d!\n"
,"svp_nnie_parse_model_header",0x1c6,0xa0338003);
}
else {
*out_buf = 0;
if (false) {
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x): the run_mode(%d) of input model should be %d!\n"
,"svp_nnie_parse_model_header",0x1d3,0xa0338003,0,0);
}
else {
out_buf[2] = 0;
if (true) {
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x): the net_seg_num(%u) of input model s hould be (0,%d]!\n"
,"svp_nnie_parse_model_header",0x1d7,0xa0338003,0,8);
}
else {
out_buf[1] = 0;
if (true) {
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x): the u32TemBufSize(%u) of input mod el can\'t be 0!\n"
,"svp_nnie_parse_model_header",0x1db,0xa0338003,0);
}
else {
if (true) {
pbVar10 = (byte *)model_buf->vir_addr;
bVar2 = *pbVar10;
size = *(uint *)(pbVar10 + 8);
out_buf[3] = (uint)bVar2;
bVar3 = pbVar10[1];
neg_counter = (ulong)bVar3;
*(ushort *)(out_buf + 4) = (ushort)bVar3;
*(ushort *)((long)out_buf + 0x12) = (ushort)pbVar10[2];
*(ushort *)(out_buf + 5) = (ushort)pbVar10[3];
uVar4 = *(ushort *)(pbVar10 + 4);
out_buf[6] = size;
size = *(uint *)(pbVar10 + 0xc);
*(ushort *)((long)out_buf + 0x16) = uVar4;
out_buf[7] = size;
if (bVar2 < 3) {
local_d8 = 0;
local_d4 = 0;
uVar15 = 0;
local_e8 = pbVar10;
if (bVar3 < 0x11) {
do {
counter = (ulong)local_d4;
lVar14 = counter * 0x69c;
uVar5 = *(ushort *)((long)out_buf + lVar14 + 0x12);
uVar9 = (ulong)uVar5;
if (0x10 < uVar5) {
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x): model->seg[%d].dst_num(% u) can\'t be greater than %u!\n"
,"svp_nnie_parse_seg_header",0x20d,0xa0338003,(ulong)local_d4,
uVar9,0x10);
goto LAB_001024b8;
}
if (4 < (ushort)out_buf[counter * 0x1a7 + 5]) {
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x): model->seg[%d].roi_pool_ num(%u) can\'t be greater than %u!\n"
,"svp_nnie_parse_seg_header",0x212,0xa0338003,(ulong)local_d4,
(ulong)(ushort)out_buf[counter * 0x1a7 + 5],4);
goto LAB_001024b8;
}
if (0x400 < uVar4) {
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x): model->seg[%d].max_step( %u) can\'t be greater than %u!\n"
,"svp_nnie_parse_seg_header",0x216,0xa0338003,(ulong)local_d4,
(ulong)(uint)uVar4,0x400);
goto LAB_001024b8;
}
uVar13 = (ulong)out_buf[counter * 0x1a7 + 6];
if (out_buf[counter * 0x1a7 + 6] != 0) {
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x): model->seg[%d].inst_offs et(%u) can\'t be greater than %u!\n"
,"svp_nnie_parse_seg_header",0x21c,0xa0338003,(ulong)local_d4,
uVar13,0);
goto LAB_001024b8;
}
if (uVar13 + size != 0) {
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x): model->seg[%d].inst_offs et(%u)+model->seg[%d].inst_len(%u) can\'t be greater than %u!\n"
,"svp_nnie_parse_seg_header",0x222,0xa0338003,(ulong)local_d4,
uVar13,(ulong)local_d4,size,0);
goto LAB_001024b8;
}
if ((int)neg_counter != 0) {
uVar9 = (ulong)local_d4;
out_buf[uVar9 * 0x1a7 + 10] = *(uint *)(local_e8 + 0x10);
out_buf[uVar9 * 0x1a7 + 9] = *(uint *)(local_e8 + 0x14);
out_buf[uVar9 * 0x1a7 + 0xb] = *(uint *)(local_e8 + 0x18);
uVar4 = *(ushort *)(local_e8 + 0x1e);
neg_counter = (ulong)uVar4;
if ((uVar4 - 2 & 0xfffd) == 0 || 5 < uVar4) {
LAB_00102388:
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x), the image type(%d) is not supported, image type can\'t be {%d, %d, %d}!\n"
,"svp_nnie_parse_src_node_info",0x248,0xa0338003,neg_counter,2
,4,6);
error = 0xa0338003;
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x): parse %d-th seg src no de failed!\n"
,"hi_mpi_svp_nnie_load_model",0x358,0xa0338003,(ulong)local_d4
);
goto joined_r0x001020c4;
}
size = 0;
uVar13 = 0;
pbVar11 = local_e8 + 0x20;
while( true ) {
uVar12 = (uint)neg_counter;
if (uVar12 == 3) {
out_buf[uVar13 * 0xd + uVar9 * 0x1a7 + 8] = 2;
sVar6 = *(short *)(pbVar11 + -4);
}
else {
if (uVar12 == 5) {
out_buf[uVar13 * 0xd + uVar9 * 0x1a7 + 8] = 3;
}
else {
out_buf[uVar13 * 0xd + uVar9 * 0x1a7 + 8] = uVar12;
}
sVar6 = *(short *)(pbVar11 + -4);
}
if (sVar6 == 1) {
uVar12 = *(uint *)(pbVar11 + -8);
out_buf[uVar13 * 0xd + uVar9 * 0x1a7 + 8] = 4;
out_buf[uVar13 * 0xd + uVar9 * 0x1a7 + 9] = uVar12;
out_buf[uVar13 * 0xd + uVar9 * 0x1a7 + 0xb] =
*(uint *)(pbVar11 + -0xc);
}
if (size == 0 && out_buf[counter * 0x1a7 + 3] == 2) {
uVar12 = *(uint *)(pbVar11 + -8);
out_buf[uVar9 * 0x1a7 + 8] = 5;
out_buf[uVar9 * 0x1a7 + 9] = uVar12;
}
neg_counter = (ulong)size;
size = size + 1;
strncpy_s(out_buf + neg_counter * 0xd + counter * 0x1a7 + 0xd,0x20,
pbVar11,0x1f);
*(undefined1 *)((long)out_buf + uVar9 * 0x69c + uVar13 * 0x34 + 0x53)
= 0;
neg_counter = (ulong)(ushort)out_buf[counter * 0x1a7 + 4];
if ((ushort)out_buf[counter * 0x1a7 + 4] <= size) break;
uVar13 = (ulong)size;
out_buf[uVar13 * 0xd + uVar9 * 0x1a7 + 10] = *(uint *)(pbVar11 + 0x30)
;
out_buf[uVar13 * 0xd + uVar9 * 0x1a7 + 9] = *(uint *)(pbVar11 + 0x34);
out_buf[uVar13 * 0xd + uVar9 * 0x1a7 + 0xb] =
*(uint *)(pbVar11 + 0x38);
uVar4 = *(ushort *)(pbVar11 + 0x3e);
neg_counter = (ulong)uVar4;
pbVar11 = pbVar11 + 0x40;
if ((uVar4 - 2 & 0xfffd) == 0 || 5 < uVar4) goto LAB_00102388;
}
uVar9 = (ulong)*(ushort *)((long)out_buf + lVar14 + 0x12);
}
if ((int)uVar9 != 0) {
if (uVar15 < 0xffffffef) {
uVar13 = (ulong)local_d4;
pbVar11 = local_e8 + neg_counter * 0x40 + 0x20;
uVar9 = 0;
LAB_00101f54:
while (pbVar10[(ulong)uVar15 + 0x11] != 1) {
uVar15 = uVar15 + 0x30;
if (uVar15 != 0) {
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x), layer_info_offset( %d) is greater than layer_info_len(%d)!\n"
,"svp_nnie_parse_dst_node_id",0x28e,0xa0338003,
(ulong)uVar15,0);
goto LAB_00102050;
}
}
uVar16 = (ulong)uVar15;
uVar15 = uVar15 + 0x30;
out_buf[uVar9 * 0xd + uVar13 * 0x1a7 + 0xdc] =
(uint)*(ushort *)(pbVar10 + uVar16 + 0x1a);
if (out_buf[counter * 0x1a7 + 3] == 2) {
if (*(short *)(pbVar11 + -4) != 1) {
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x), if net type is %d, the %d-th report data should be tensor!\n"
,"svp_nnie_parse_dst_node_info",700,0,
(ulong)out_buf[counter * 0x1a7 + 3],uVar9);
uVar9 = (ulong)*(ushort *)((long)out_buf + lVar14 + 0x12);
sVar6 = (short)out_buf[counter * 0x1a7 + 5];
goto joined_r0x0010243c;
}
if (*(short *)(pbVar11 + -2) == 1) {
out_buf[uVar9 * 0xd + uVar13 * 0x1a7 + 0xd9] =
*(uint *)(pbVar11 + -0x10);
out_buf[uVar9 * 0xd + uVar13 * 0x1a7 + 0xd8] = 5;
}
else {
out_buf[uVar9 * 0xd + uVar13 * 0x1a7 + 0xda] = 1;
out_buf[uVar9 * 0xd + uVar13 * 0x1a7 + 0xdb] = 1;
out_buf[uVar9 * 0xd + uVar13 * 0x1a7 + 0xd8] = 4;
out_buf[uVar9 * 0xd + uVar13 * 0x1a7 + 0xd9] =
*(uint *)(pbVar11 + -0x10);
}
}
else {
out_buf[uVar9 * 0xd + uVar13 * 0x1a7 + 0xda] =
*(uint *)(pbVar11 + -0x10);
out_buf[uVar9 * 0xd + uVar13 * 0x1a7 + 0xd9] =
*(uint *)(pbVar11 + -0xc);
out_buf[uVar9 * 0xd + uVar13 * 0x1a7 + 0xdb] =
*(uint *)(pbVar11 + -8);
if (*(short *)(pbVar11 + -4) == 0) {
out_buf[uVar9 * 0xd + uVar13 * 0x1a7 + 0xdb] =
*(uint *)(pbVar11 + -0xc);
size = *(uint *)(pbVar11 + -8);
out_buf[uVar9 * 0xd + uVar13 * 0x1a7 + 0xd8] = 4;
out_buf[uVar9 * 0xd + uVar13 * 0x1a7 + 0xd9] = size;
}
else {
if (*(short *)(pbVar11 + -4) != 1) {
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x), report node mode shoule be 0 or 1!\n"
,"svp_nnie_parse_dst_node_info",0x2d6,0);
uVar9 = (ulong)*(ushort *)((long)out_buf + lVar14 + 0x12);
goto LAB_0010218c;
}
out_buf[uVar9 * 0xd + uVar13 * 0x1a7 + 0xd8] = 0;
}
}
size = (int)uVar9 + 1;
uVar16 = (ulong)size;
strncpy_s(out_buf + uVar9 * 0xd + counter * 0x1a7 + 0xdd,0x20,pbVar11,
0x1f);
*(undefined1 *)((long)out_buf + uVar13 * 0x69c + uVar9 * 0x34 + 0x393)
= 0;
uVar4 = *(ushort *)((long)out_buf + lVar14 + 0x12);
uVar9 = (ulong)uVar4;
if (uVar4 <= size) goto LAB_0010218c;
pbVar11 = pbVar11 + 0x40;
uVar9 = uVar16;
if (0xffffffee < uVar15) goto LAB_0010201c;
goto LAB_00101f54;
}
uVar16 = 0;
LAB_0010201c:
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x), layer_info_offset(%d) sh ould be less than %d!\n"
,"svp_nnie_parse_dst_node_id",0x288,0xa0338003,(ulong)uVar15,
0xffffffef);
uVar9 = uVar16;
LAB_00102050:
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x), %d-th node, svp_nnie_par se_dst_node_id failed!\n"
,"svp_nnie_parse_dst_node_info",0x2b5,0xa0338003,uVar9);
error = 0xa0338003;
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x): parse %d-th seg dst node failed!\n"
,"hi_mpi_svp_nnie_load_model",0x360,0xa0338003,(ulong)local_d4);
goto joined_r0x001020c4;
}
LAB_0010218c:
sVar6 = (short)out_buf[counter * 0x1a7 + 5];
joined_r0x0010243c:
lVar14 = uVar9 * 0x40 + neg_counter * 0x40 + 0x10;
if (sVar6 == 0) {
uVar4 = 0;
}
else {
neg_counter = 0;
pbVar11 = local_e8 + lVar14 + 0x40;
size = local_d8;
do {
out_buf[(ulong)local_d4 * 0x1a7 + neg_counter + 0x1a8] = size;
uVar12 = (int)neg_counter + 1;
neg_counter = (ulong)uVar12;
local_d8 = size + 1;
out_buf[(ulong)size * 0x1a + 0xd48] = *(uint *)(pbVar11 + -0x40);
out_buf[(ulong)size * 0x1a + 0xd3b] = *(uint *)(pbVar11 + -0x3c);
out_buf[(ulong)size * 0x1a + 0xd3c] = *(uint *)(pbVar11 + -0x38);
out_buf[(ulong)size * 0x1a + 0xd47] = *(uint *)(pbVar11 + -0x34);
out_buf[(ulong)size * 0x1a + 0xd3e] = *(uint *)(pbVar11 + -0x30);
out_buf[(ulong)size * 0x1a + 0xd3f] = *(uint *)(pbVar11 + -0x2c);
out_buf[(ulong)size * 0x1a + 0xd3d] = *(uint *)(pbVar11 + -0x28);
out_buf[(ulong)size * 0x1a + 0xd40] = *(uint *)(pbVar11 + -0x24);
out_buf[(ulong)size * 0x1a + 0xd46] = *(uint *)(pbVar11 + -0x20);
out_buf[(ulong)size * 0x1a + 0xd45] = *(uint *)(pbVar11 + -0x1c);
out_buf[(ulong)size * 0x1a + 0xd41] = *(uint *)(pbVar11 + -0x18);
out_buf[(ulong)size * 0x1a + 0xd42] = *(uint *)(pbVar11 + -0x14);
out_buf[(ulong)size * 0x1a + 0xd43] = *(uint *)(pbVar11 + -0x10);
out_buf[(ulong)size * 0x1a + 0xd44] = *(uint *)(pbVar11 + -0xc);
out_buf[(ulong)size * 0x1a + 0xd49] = (uint)pbVar11[-8];
out_buf[(ulong)size * 0x1a + 0xd4b] = (uint)pbVar11[-7];
out_buf[(ulong)size * 0x1a + 0xd4c] = (uint)pbVar11[-6];
out_buf[(ulong)size * 0x1a + 0xd4a] = (uint)pbVar11[-5];
strncpy_s(out_buf + (ulong)size * 0x1a + 0xd4d,0x20,pbVar11,0x1f);
*(undefined1 *)((long)out_buf + (ulong)size * 0x68 + 0x3553) = 0;
uVar4 = (ushort)out_buf[counter * 0x1a7 + 5];
pbVar11 = pbVar11 + 0x70;
size = local_d8;
} while (uVar12 < uVar4);
}
local_d4 = local_d4 + 1;
local_e8 = local_e8 + (int)((uint)uVar4 * 0x70) + lVar14;
if (out_buf[2] <= local_d4) {
error = 0;
vir_addr = model_buf->phy_addr;
uVar1 = model_buf->vir_addr;
out_buf[0xda8] = 0;
*(uint64_t *)(out_buf + 0xda4) = vir_addr;
*(uint64_t *)(out_buf + 0xda6) = uVar1;
iVar8 = svp_nnie_check_model_user(out_buf);
if (iVar8 != 0) {
error = 0xa0338003;
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x), SVP_NNIE_CheckModelUse r failed!\n"
,"hi_mpi_svp_nnie_load_model",0x371,0xa0338003);
}
goto joined_r0x001020c4;
}
bVar2 = *local_e8;
out_buf[(ulong)local_d4 * 0x1a7 + 3] = (uint)bVar2;
*(ushort *)(out_buf + (ulong)local_d4 * 0x1a7 + 4) = (ushort)local_e8[1];
*(ushort *)((long)out_buf + (ulong)local_d4 * 0x69c + 0x12) =
(ushort)local_e8[2];
*(ushort *)(out_buf + (ulong)local_d4 * 0x1a7 + 5) = (ushort)local_e8[3];
uVar4 = *(ushort *)(local_e8 + 4);
*(ushort *)((long)out_buf + (ulong)local_d4 * 0x69c + 0x16) = uVar4;
out_buf[(ulong)local_d4 * 0x1a7 + 6] = *(uint *)(local_e8 + 8);
size = *(uint *)(local_e8 + 0xc);
out_buf[(ulong)local_d4 * 0x1a7 + 7] = size;
if (2 < bVar2) goto LAB_0010247c;
neg_counter = (ulong)(ushort)out_buf[(ulong)local_d4 * 0x1a7 + 4];
} while ((ushort)out_buf[(ulong)local_d4 * 0x1a7 + 4] < 0x11);
}
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x): model->seg[%d].src_num(%u) can \'t be greater than %u!\n"
,"svp_nnie_parse_seg_header",0x209,0xa0338003,(ulong)local_d4,
neg_counter,0x10);
}
else {
local_d4 = 0;
LAB_0010247c:
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x): model->seg[%d].net_type(%d) sh ould be [%d,%d)!\n"
,"svp_nnie_parse_seg_header",0x205,0xa0338003,(ulong)local_d4,
(ulong)bVar2,0,3);
}
LAB_001024b8:
error = 0xa0338003;
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x): parse %d-th seg head info failed !\n"
,"hi_mpi_svp_nnie_load_model",0x352,0xa0338003,(ulong)local_d4);
goto joined_r0x001020c4;
}
fprintf(_stderr,
"[Func]:%s [Line]:%d [Info]:Error(%#x): model_buf->size(%u) can\'t be less than %llu!\n"
,"svp_nnie_parse_model_header",0x1e0,0xa0338003);
}
}
}
}
}
else {
fprintf(_stderr,"[Func]:%s [Line]:%d [Info]:Error(%#x): check file failed!\n",
"svp_nnie_parse_model_header",0x1b5,0xa0338003);
}
}
error = 0xa0338003;
fprintf(_stderr,"[Func]:%s [Line]:%d [Info]:Error(%#x): check model head info failed!\n",
"hi_mpi_svp_nnie_load_model",0x347,0xa0338003);
}
}
else {
fprintf(_stderr,"[Func]:%s [Line]:%d [Info]:Error(%#x): check model input param failed!\n",
"hi_mpi_svp_nnie_load_model",0x340,(ulong)error);
}
joined_r0x001020c4:
if (lVar7 == ___stack_chk_guard) {
return;
}
/* WARNING: Subroutine does not return */
__stack_chk_fail(error);
}Cory wanted to know why the decompiler had simplified certain branch conditions
to true or false, such as the one on line 47. Seeing true or false
branch conditions is somewhat rare in decompilers since compilers often perform
these types of optimizations. My first issue was that my decompilation output
looked much shorter than his:
/* WARNING: Removing unreachable block (ram,0x00101c60) */
/* WARNING: Removing unreachable block (ram,0x001026f8) */
/* WARNING: Removing unreachable block (ram,0x00101c6c) */
/* WARNING: Removing unreachable block (ram,0x0010272c) */
/* WARNING: Removing unreachable block (ram,0x00101c58) */
/* WARNING: Removing unreachable block (ram,0x001026c8) */
/* WARNING: Removing unreachable block (ram,0x00101c8c) */
/* WARNING: Removing unreachable block (ram,0x00101cb0) */
/* WARNING: Removing unreachable block (ram,0x00102478) */
/* WARNING: Removing unreachable block (ram,0x00101d0c) */
/* WARNING: Removing unreachable block (ram,0x00101d1c) */
/* WARNING: Removing unreachable block (ram,0x0010264c) */
/* WARNING: Removing unreachable block (ram,0x00101d38) */
/* WARNING: Removing unreachable block (ram,0x00102614) */
/* WARNING: Removing unreachable block (ram,0x00101d44) */
/* WARNING: Removing unreachable block (ram,0x001025d8) */
/* WARNING: Removing unreachable block (ram,0x00101d4c) */
/* WARNING: Removing unreachable block (ram,0x001025a0) */
/* WARNING: Removing unreachable block (ram,0x00101d5c) */
/* WARNING: Removing unreachable block (ram,0x00102560) */
/* WARNING: Removing unreachable block (ram,0x00101d6c) */
/* WARNING: Removing unreachable block (ram,0x00101d70) */
/* WARNING: Removing unreachable block (ram,0x00101db0) */
/* WARNING: Removing unreachable block (ram,0x00101db4) */
/* WARNING: Removing unreachable block (ram,0x00101db8) */
/* WARNING: Removing unreachable block (ram,0x00101e9c) */
/* WARNING: Removing unreachable block (ram,0x00101dd8) */
/* WARNING: Removing unreachable block (ram,0x00101ef0) */
/* WARNING: Removing unreachable block (ram,0x00101de0) */
/* WARNING: Removing unreachable block (ram,0x00101de4) */
/* WARNING: Removing unreachable block (ram,0x00101eb4) */
/* WARNING: Removing unreachable block (ram,0x00101ec8) */
/* WARNING: Removing unreachable block (ram,0x00101df0) */
/* WARNING: Removing unreachable block (ram,0x00101df8) */
/* WARNING: Removing unreachable block (ram,0x00101dfc) */
/* WARNING: Removing unreachable block (ram,0x00101e00) */
/* WARNING: Removing unreachable block (ram,0x00101e10) */
/* WARNING: Removing unreachable block (ram,0x00101efc) */
/* WARNING: Removing unreachable block (ram,0x00101f00) */
/* WARNING: Removing unreachable block (ram,0x00101f1c) */
/* WARNING: Removing unreachable block (ram,0x00101f2c) */
/* WARNING: Removing unreachable block (ram,0x00101f54) */
/* WARNING: Removing unreachable block (ram,0x00101f48) */
/* WARNING: Removing unreachable block (ram,0x001020d0) */
/* WARNING: Removing unreachable block (ram,0x00101f64) */
/* WARNING: Removing unreachable block (ram,0x00102118) */
/* WARNING: Removing unreachable block (ram,0x001023f8) */
/* WARNING: Removing unreachable block (ram,0x00102124) */
/* WARNING: Removing unreachable block (ram,0x0010214c) */
/* WARNING: Removing unreachable block (ram,0x00102130) */
/* WARNING: Removing unreachable block (ram,0x00101f90) */
/* WARNING: Removing unreachable block (ram,0x00102108) */
/* WARNING: Removing unreachable block (ram,0x00102160) */
/* WARNING: Removing unreachable block (ram,0x00102110) */
/* WARNING: Removing unreachable block (ram,0x00101fb0) */
/* WARNING: Removing unreachable block (ram,0x00101fc8) */
/* WARNING: Removing unreachable block (ram,0x0010200c) */
/* WARNING: Removing unreachable block (ram,0x00102558) */
/* WARNING: Removing unreachable block (ram,0x0010201c) */
/* WARNING: Removing unreachable block (ram,0x00102050) */
/* WARNING: Removing unreachable block (ram,0x0010218c) */
/* WARNING: Removing unreachable block (ram,0x00102440) */
/* WARNING: Removing unreachable block (ram,0x001021a4) */
/* WARNING: Removing unreachable block (ram,0x001021bc) */
/* WARNING: Removing unreachable block (ram,0x001022a8) */
/* WARNING: Removing unreachable block (ram,0x001024f0) */
/* WARNING: Removing unreachable block (ram,0x00102520) */
/* WARNING: Removing unreachable block (ram,0x001022d8) */
/* WARNING: Removing unreachable block (ram,0x0010247c) */
/* WARNING: Removing unreachable block (ram,0x00102338) */
/* WARNING: Removing unreachable block (ram,0x00101e50) */
/* WARNING: Removing unreachable block (ram,0x00101e94) */
/* WARNING: Removing unreachable block (ram,0x00101e98) */
/* WARNING: Removing unreachable block (ram,0x00102388) */
/* WARNING: Removing unreachable block (ram,0x00102348) */
/* WARNING: Removing unreachable block (ram,0x001024b8) */
/* WARNING: Removing unreachable block (ram,0x00102800) */
/* WARNING: Removing unreachable block (ram,0x00101c80) */
/* WARNING: Removing unreachable block (ram,0x001027cc) */
/* WARNING: Removing unreachable block (ram,0x00102688) */
/* WARNING: Removing unreachable block (ram,0x0010279c) */
/* WARNING: Globals starting with '_' overlap smaller symbols at the same address */

void HI_MPI_SVP_NNIE_LoadModel(model *model_buf,uint *out_buf,ulong param3)

{
  long lVar1;
  uint32_t error;
  int flag;
  ulong neg_counter;
  byte *pbVar2;
  uint64_t vir_addr;
  header header_buf;
  byte *pbVar3;
  uint size;

  lVar1 = ___stack_chk_guard;
  _header_buf = 0;
  error = svp_nnie_check_loadmodel_param_user(model_buf,(long)out_buf);
  if (error == 0) {
    size = (uint)model_buf->size;
    if (size < 0xc1) {
      error = 0xa0338003;
      fprintf(_stderr,
              "[Func]:%s [Line]:%d [Info]:Error(%#x): model_buf->size(%u) must be greater than %u!\n "
              ,"hi_mpi_svp_nnie_load_model",0x345,0xa0338003,(ulong)size,0xc0);
    }
    else {
      vir_addr = model_buf->vir_addr;
      memcpy_s(&header_buf,0xc0,vir_addr);
      neg_counter = 0;      pbVar3 = (byte *)(vir_addr + 4);
      do {
        pbVar2 = pbVar3 + 1;
        size = *(uint *)(&DAT_00105d70 + ((neg_counter ^ *pbVar3) & 0xff) * 4) ^
               (uint)neg_counter >> 8;
        neg_counter = (ulong)size;
        pbVar3 = pbVar2;
      } while ((byte *)(vir_addr + 0x100000000) != pbVar2);
      if (header_buf.unk1 == ~size) {
        memset_s(out_buf,0x36a8,0);
        fprintf(_stderr,
                "[Func]:%s [Line]:%d [Info]:Error(%#x):model_version(%u) of input model should be %d !\n"
                ,"svp_nnie_parse_model_header",0x1c3,0xa0338003,0,0xb);
      }
      else {
        fprintf(_stderr,"[Func]:%s [Line]:%d [Info]:Error(%#x): check file failed!\n",
                "svp_nnie_parse_model_header",0x1b5,0xa0338003);
      }
      error = 0xa0338003;
      fprintf(_stderr,"[Func]:%s [Line]:%d [Info]:Error(%#x): check model head info failed!\n",
              "hi_mpi_svp_nnie_load_model",0x347,0xa0338003);
    }
  }
  else {
    fprintf(_stderr,"[Func]:%s [Line]:%d [Info]:Error(%#x): check model input param failed!\n",
            "hi_mpi_svp_nnie_load_model",0x340,(ulong)error);
  }
  if (lVar1 == ___stack_chk_guard) {
    return;
  }
                    /* WARNING: Subroutine does not return */
  __stack_chk_fail(error);
}
We figured out that I had the "Eliminate unreachable code" option enabled under Ghidra's Options => Decompiler => Analysis options tab, but he did not.
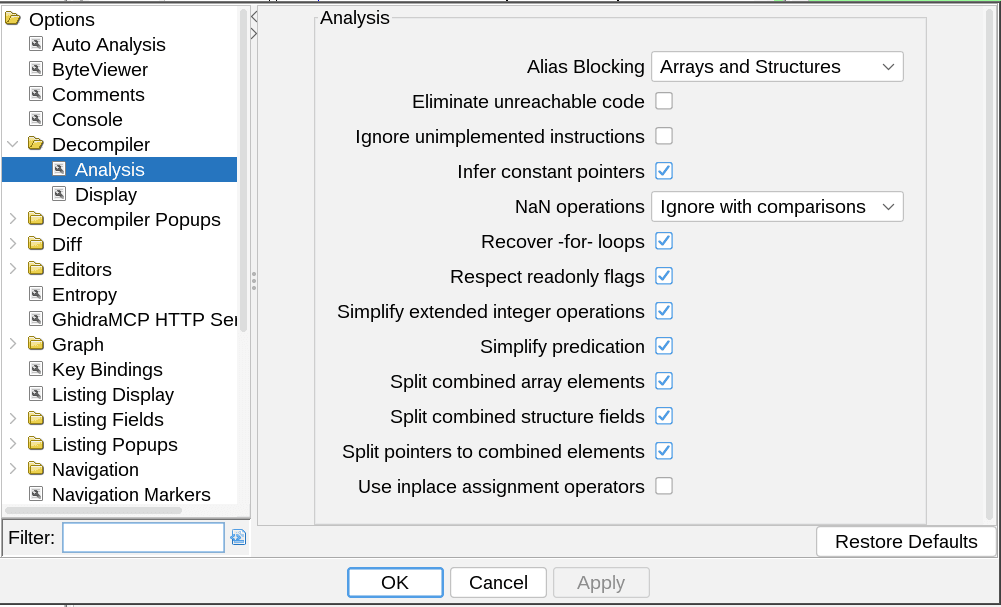
if (false) { ... }
statement was unreachable code and removed it.
With that small mystery solved, I obtained the same decompilation as Cory, but we still didn't know why Ghidra had simplified away the condition. This task was made a lot more challenging since it was an ARM executable, and neither of us are very familiar with ARM assembly code. Cory eventually figured out that on the same decompiler settings tab, changing the "Alias Blocking" option from "Arrays and Structures" to "None" caused Ghidra to preserve the original condition.
Ghidra's documentation on Alias Blocking explains:
When deciding if an individual stack location has become dead, the Decompiler must consider aliases, pointers onto the stack that could be used to modify the location within a called function. One strong heuristic the Decompiler uses is: if the user has explicitly created a variable on the stack between the base location referenced by the pointer and the individual stack location, then the Decompiler can assume that the pointer is not an alias of the stack location. The alias is blocked by the explicit variable. However, if the user's explicit variable is labeling something that isn't really an explicit variable, like a field within a larger structure, for instance, the Decompiler may incorrectly consider the stack location as dead and start removing live code.
In order to support the exploratory labeling of stack locations, the user can use this setting to specify what data-types should be considered blocking. The four options are:
- None - No data-type is considered blocking
- Structures - Only structures are blocking
- Structures and Arrays - Only structures and arrays are blocking
- All Data-types - All data-types are blocking
Selecting None is the equivalent of turning off the heuristic. Selecting anything except All Data-types allows users to safely label small variables without knowing immediately if the stack location is part of a larger structure or array.
To better understand what is going on, here is one of the relevant snippets that went from false to a real condition:
    else {
      vir_addr = model_buf->vir_addr;
      memcpy_s(&header_buf,0xc0,vir_addr);
      size = local_98._4_4_ + (uint)uStack_90;      if ((uint)model_buf->size < size) {        fprintf(_stderr,
                "[Func]:%s [Line]:%d [Info]:Error(%#x): model_buf->size(%d) is less than %d!\n",
                "svp_nnie_parse_model_header",0x1b2,0xa0338003);
      }
Looking at the stack frame, we can start to piece together what happened:
local_98anduStack_90were initialized to zero.memcpy_swas called with a pointer toheader_buf, which is a structure of size 0xc0 bytes on the stack.- Since
header_bufis a structure, Alias Blocking with "Arrays and Structures" enabled means that Ghidra assumes thatlocal_98anduStack_90cannot be modified by thememcpy_scall, since they are not part of theheader_bufstructure. Therefore, Ghidra concludes that they are unchanged,sizeis always zero, and the condition is alwaysfalse.
Unfortunately for Cory, the header_buf structure he created was only four
bytes long. In reality, local_98 and uStack_90 are fields that are
overwritten by the memcpy_s call, and influence the computation of the
condition. But his artificially small structure misled Ghidra into thinking
they were unaffected.
So What?
I had never heard of the "Alias Blocking" option before, and I'm not aware of a
similar feature in other decompilers. It's an interesting idea though.
Basically, the assumption is that if you have enough information to type an
array or structure on the stack, then it is accurate enough to assume there
won't be pointers from that object that alias outside of that object. There's
also a number of other things that have to work correctly for this analysis to
be correct. If we had confused the calling convention of memcpy_s and did not
detect that it takes a pointer to the stack, then this analysis would also be
incorrect.
It's also interesting because it has the potential to both help and hurt decompilation quality, depending on the situation. Cory noted this functionality could be helpful for deobfuscating opaque predicates, for example. But Cory also noted that he often retypes structs incrementally as he learns more about them. Alias Blocking on structures would actually be harmful for this type of incremental typing.
Anti-analysis?
Another interesting question is whether we can abuse this behavior to make it harder to analyze code. To answer this, I created a small test program that can exhibit the same behavior. Here it is (also on Godbolt):
#include <string.h>
#include <stdio.h>

struct foo {
  int blue;
  int red;
  char green;
  float two;
};

void go(struct foo* in) {
    int above = -1;
    struct foo myfoo;
    myfoo.red = 0;
    int below = 2;
    memcpy(&myfoo, in, sizeof(myfoo));
    if (myfoo.red != 10) {
        printf("Wow!\n");
    }
}

int main() {
    struct foo mainfoo = {4, 5, 'a', 3.14};
}
I found that I had to compile with gcc -fno-builtin or otherwise gcc would fairly aggressively optimize away the memcpy call!
Upon initially loading Ghidra, the decompilation of the go function looks like this:
/* WARNING: Unknown calling convention -- yet parameter storage is locked */

long go(void)

{
  void *in_RDI;
  long in_FS_OFFSET;
  undefined1 local_28 [4];
  int local_24;
  long local_10;

  local_10 = *(long *)(in_FS_OFFSET + 0x28);
  local_24 = 0;
  memcpy(local_28,in_RDI,0x10);
  if (local_24 != 10) {
    printf("Wow!\n");
  }
  if (local_10 != *(long *)(in_FS_OFFSET + 0x28)) {
                    /* WARNING: Subroutine does not return */
    __stack_chk_fail();
  }
  return 0;
}
For some reason undefined1[4] is not considered to be an Array type. But if
we manually retype local_28 to char[4] instead of undefined1[4], we see
the desired behavior:
/* WARNING: Unknown calling convention -- yet parameter storage is locked */

long go(void)

{
  long lVar1;
  void *in_RDI;
  long in_FS_OFFSET;
  char local_28 [4];

  lVar1 = *(long *)(in_FS_OFFSET + 0x28);
  memcpy(local_28,in_RDI,0x10);
  if (true) {
    printf("Wow!\n");
  }
  if (lVar1 != *(long *)(in_FS_OFFSET + 0x28)) {
                    /* WARNING: Subroutine does not return */
    __stack_chk_fail();
  }
  return 0;
}
Of course, we could have made that condition appear to be false.
If we could nudge Ghidra to type local_28 as a char[4] array automatically,
or a structure, perhaps we could automatically cause Ghidra to misinterpret the
condition. The alias blocking documentation suggests that it only applies when a
user "explicitly" creates a variable on the stack, so this might prevent abuse
for anti-analysis. I leave this as an open question for the reader.


Systematic Testing of C++ Abstraction Recovery Systems by Iterative Compiler Model Refinement
I'm excited to announce that our paper, "Systematic Testing of C++ Abstraction Recovery Systems by Iterative Compiler Model Refinement", has been published at the 2025 Workshop on Software Understanding and Reverse Engineering (SURE)! SURE is a new workshop—more details below.
When I joined SEI, one of my first research projects was improving C++ abstraction recovery from binaries. This work led to the development of OOAnalyzer, a tool that combines practical reverse engineering with academic techniques like a Prolog-based reasoning engine.
Over time, users increasingly adopted OOAnalyze and ran it on video game executables that were much larger and more complex than the malware samples we had originally targeted. Perhaps unsurprisingly, running OOAnalyzer on these larger, more complex binaries often revealed problematic corner cases in OOAnalyzer's rules. As we learned about such problems, we would attempt to improve the rules to handle the new cases. Sometimes this was pretty easy; some of the problems were obvious in hindsight. But not always.
Eventually, I found that some rules were becoming so nuanced and complex that I was having trouble reasoning about them. I realized that I needed a more systematic way to test and refine OOAnalyzer's rules. This realization led to the work presented in this paper.
On one hand, I'm incredibly proud of this paper. To greatly simplify, we developed a way to model check the rules in OOAnalyzer. It's been incredibly effective at finding problems in OOAnalyzer's rules. We found 27 soundness issues in OOAnalyzer, and two in VirtAnalyzer, a competing C++ abstraction recovery system.
Unfortunately, the journey to publication for this paper has been long and bumpy. It is, admittedly, a fairly niche topic. But I also think it has some interesting ideas that could be applied more generally to other reverse engineering systems. In particular, I think that much of what we call "binary analysis" is actually "compiled executable analysis" in disguise. In other words, our binary analyses are often making (substantial!) assumptions about how compilers work, such as the calling conventions that are used, and without these assumptions they do not work. Our paper provides a systematic way to encode and refine these assumptions, and validate whether underlying analyses are correct under the assumptions. My hope is that in future work, we are able to demonstrate how to apply this overall approach to more traditional binary analyses. I personally think that static binary analysis without such reasonable simplifying assumptions is impractical, so we need more techniques like this to help analyze compiled executables.
Although I'm proud of the problems we discovered in OOAnalyzer, I'm also a bit disappointed in the practical impact. My hope was that when we found and fixed soundness problems in OOAnalyzer's rules, it would generally improve the performance of OOAnalyzer on real-world binaries. However, we found that in general this was not true. In fact, in some cases, fixing soundness problems actually made OOAnalyzer perform worse on real-world binaries! I think this highlights that there is a trade-off between soundness and accuracy in binary analysis. In order to be sound, the system can never make mistakes. We may need to make a rule more conservative, even if it almost never poses a problem in practice. However, in order to maximize accuracy, the system must optimize for the most common cases, even if it means that it will occasionally make mistakes.
SURE Workshop
SURE, the Workshop on Software Understanding and Reverse Engineering, is a new workshop colocated with ACM CCS this year. In addition to presenting our paper, I had the honor of participating in a panel on "Modern Software Understanding" alongside Fish Wang and Steffen Enders. The first SURE was a resounding success, and I'm eager to see how it evolves in the coming years!
🎉 New Research Published at DIMVA 2025
I'm excited to announce that "Quantifying and Mitigating the Impact of Obfuscations on Machine-Learning-Based Decompilation Improvement" has been published at the 2025 Conference on Detection of Intrusions and Malware & Vulnerability Assessment (DIMVA 2025)!
The Research Team
This work was primarily conducted by Deniz Bölöni-Turgut—a bright undergraduate at Cornell University—as part of the REU in Software Engineering (REUSE) program at CMU. She was supervised by Luke Dramko from our research group.
What We Investigated
This paper tackles an important question in the evolving landscape of AI-powered reverse engineering: How do code obfuscations impact the effectiveness of these ML-based approaches? In the real world, adversaries often employ obfuscation techniques to make their code harder to analyze by reverse engineers. Although these obfuscation techniques were not designed with machine learning in mind, they can significantly modify the code, which raises the question of whether they could hinder the performance of ML models, which are currently trained on unobfuscated code.
Key Findings
Our research provides important quantitative insights into how obfuscations affect ML-based decompilation:
-
Obfuscations do negatively impact ML models: We demonstrated that semantics-preserving transformations that obscure program functionality significantly reduce the accuracy of machine learning-based decompilation tools.
-
Training on obfuscated code helps: Our experiments show that training models on obfuscated code can partially recover the lost accuracy, making the tools more resilient to obfuscation techniques.
-
Consistent results across multiple models: We validated our findings across three different state-of-the-art models from the literature—DIRTY, HexT5, and VarBERT—suggesting that our findings generalize.
-
Practical implications for malware analysis: Since obfuscations are commonly used in malware, these findings are directly applicable to improving real-world binary analysis scenarios.
This work represents an important step forward in making ML-based decompilation tools more resilient against the obfuscation techniques commonly encountered in real-world binary analysis scenarios. As the field continues to evolve, understanding these vulnerabilities and developing robust solutions will be crucial for maintaining the effectiveness of AI-powered security tools.
Read More
Want to know more? Download the complete paper.
🎉 New Research Published at DSN 2025
I'm excited to announce that "A Human Study of Automatically Generated Decompiler Annotations" has been published at the 2025 IEEE/IFIP International Conference on Dependable Systems and Networks (DSN 2025)!
The Research Team
This work represents the culmination of Jeremy Lacomis's Ph.D. research, alongside our fantastic collaborators:
- Vanderbilt University: Yuwei Yang, Skyler Grandel, and Kevin Leach
- Carnegie Mellon University: Bogdan Vasilescu and Claire Le Goues
What We Studied
This paper investigates a critical question in reverse engineering: Do automatically generated variable names and type annotations actually help human analysts understand decompiled code?
Our study built upon DIRTY, our machine learning system that automatically generates meaningful variable names and type information for decompiled binaries. While DIRTY showed promising technical results, we wanted to understand its real-world impact on human reverse engineers.
Key Findings
- Surprisingly, the annotations did not significantly improve participants' task completion speed or accuracy
- This challenges assumptions about the direct correlation between code readability and task performance
- Participants preferred code with annotations over plain decompiled output
Read More
Interested in the full methodology and detailed results? Download the complete paper to dive deeper into our human study design, statistical analysis, and implications for future decompilation tools.
Many people seem to be unaware that decompilers have a decompilation export feature, which is particularly beneficial when you are trying to parse or recompile decompiled code.
Ghidra
Here is a random function from /bin/ls that I decompiled using Ghidra, and simply copied the output from the decompilation window:
void FUN_0010b1b0(undefined8 *param_1,undefined8 *param_2)

{
  char *__s;
  char *__s_00;
  int iVar1;
  char *__s1;
  char *__s2;
  int *piVar2;

  __s = (char *)*param_2;
  __s1 = strrchr(__s,0x2e);
  __s_00 = (char *)*param_1;
  __s2 = strrchr(__s_00,0x2e);
  if (__s2 == (char *)0x0) {
    __s2 = "";
  }
  if (__s1 == (char *)0x0) {
    __s1 = "";
  }
  piVar2 = __errno_location();
  *piVar2 = 0;
  iVar1 = strcoll(__s1,__s2);
  if (iVar1 == 0) {
    strcoll(__s,__s_00);
    return;
  }
  return;
}
This code does not compile.
gcc -c a.c
a.c:1:19: error: unknown type name ‘undefined8’
    1 | void FUN_0010b1b0(undefined8 *param_1,undefined8 *param_2)
      |                   ^~~~~~~~~~
a.c:1:39: error: unknown type name ‘undefined8’
    1 | void FUN_0010b1b0(undefined8 *param_1,undefined8 *param_2)
      |                                       ^~~~~~~~~~
However, we can use Ghidra's decompiler exporter to decompile the function AND emit a header file that will define the types and declare the functions used in the decompiled code. Unfortunately, this is a little bit awkward to do for one function. I suggest the following process:
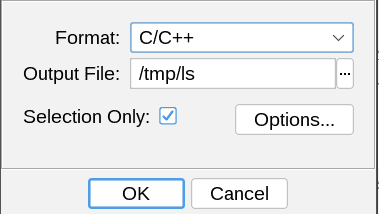
- In the CodeBrowser, select the function you want to decompile in the Listing (disassembly) window.
- In the CodeBrowser, navigate to File → Export Program.
- Select "C/C++" as the Format.
- Ensure that the "Selection Only" checkbox is checked.
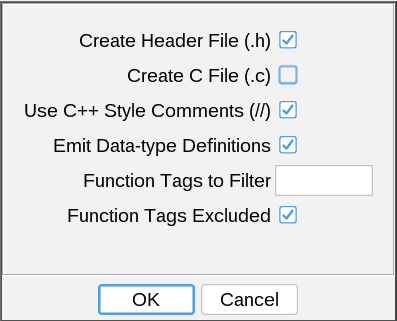
- In the Options dialog, check both the "Create Header File (.h)" and "Create C File (.c)" options.
- Click OK.
This will create a decompiled source file ls.c containing type definitions for types used in the decompiled code, such as undefined8.
And if you try to compile the generated ls.c file, it will compile successfully:
gcc -c ls.c
ls.c: In function ‘FUN_0010b1b0’:
ls.c:630:10: warning: implicit declaration of function ‘strrchr’ [-Wimplicit-function-declaration]
  630 |   __s1 = strrchr(__s,0x2e);
      |          ^~~~~~~
ls.c:1:1: note: include ‘<string.h>’ or provide a declaration of ‘strrchr’
  +++ |+#include <string.h>
    1 | typedef unsigned char   undefined;
ls.c:630:10: warning: incompatible implicit declaration of built-in function ‘strrchr’ [-Wbuiltin-declaration-mismatch]
  630 |   __s1 = strrchr(__s,0x2e);
      |          ^~~~~~~
ls.c:630:10: note: include ‘<string.h>’ or provide a declaration of ‘strrchr’
ls.c:639:12: warning: implicit declaration of function ‘__errno_location’ [-Wimplicit-function-declaration]
  639 |   piVar2 = __errno_location();
      |            ^~~~~~~~~~~~~~~~
ls.c:639:10: warning: assignment to ‘int *’ from ‘int’ makes pointer from integer without a cast [-Wint-conversion]
  639 |   piVar2 = __errno_location();
      |          ^
ls.c:641:11: warning: implicit declaration of function ‘strcoll’ [-Wimplicit-function-declaration]
  641 |   iVar1 = strcoll(__s1,__s2);
      |           ^~~~~~~
Hurray!
This is slightly oversimplified. You can see the compiler's warnings that we did not have declarations for strrchr, __errno_location, and strcoll. Ghidra can generate these declarations, but didn't because we used the "Selection Only" option. To get these declarations, you can use an approach like the following:
- Use "Export Program" to export the entire program. Under the "Options" dialog, check only the "Create Header File (.h)" option.
- Use "Export Program" to export only the function you care about, but this time check only the "Create C File (.c)" option.
- Remove type definitions from the generated C file, and instead include the generated header file.
- Cross your fingers.
Unfortunately, this header file does not always compile. Here are some errors that I obtained when trying to compile the header for /bin/ls:
In file included from FUN_0010b1b0.c:1:
FUN_0010b1b0.h:671:6: warning: conflicting types for built-in function ‘__snprintf_chk’; expected ‘int(char *, long unsigned int,  int,  long unsigned int,  const char *, ...)’ [-Wbuiltin-declaration-mismatch]
  671 | void __snprintf_chk(void);
      |      ^~~~~~~~~~~~~~
FUN_0010b1b0.h:682:5: error: ‘sigaction’ redeclared as different kind of symbol
  682 | int sigaction(int __sig,sigaction *__act,sigaction *__oact);
      |     ^~~~~~~~~
FUN_0010b1b0.h:294:26: note: previous declaration of ‘sigaction’ with type ‘sigaction’
  294 | typedef struct sigaction sigaction, *Psigaction;
      |                          ^~~~~~~~~
FUN_0010b1b0.h:695:6: warning: conflicting types for built-in function ‘dcgettext’; expected ‘char *(const char *, const char *, int)’ [-Wbuiltin-declaration-mismatch]
  695 | void dcgettext(void);
      |      ^~~~~~~~~
[truncated]
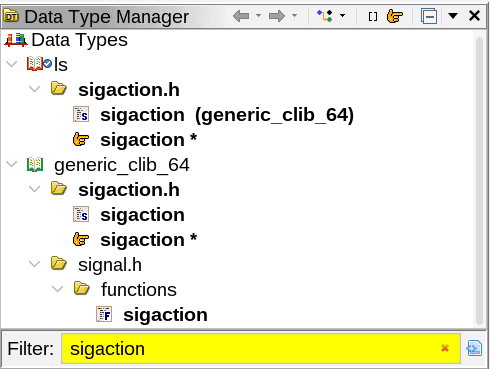
This is probably because Ghidra's type manager includes multiple definitions for
some types, such as sigaction. I have opened a Ghidra
issue for these
problems. Hopefully the Ghidra developers will commit to fixing these problems
in the header file, since it would significantly improve the usability of the
decompiler output.
Here is a ghidra-scala-loader script that can do the above steps for you from the command line.
Hex-Rays
IDA/Hex-Rays has a similar feature, but it is much more straightforward. Simply select File → Create C File, and it will generate a C file that includes all the necessary type definitions and function declarations. It does include defs.h, which is a file that contains type definitions for Hex-Rays. You can find that in the Hex-Rays SDK or elsewhere.
Can existing neural decompiler artifacts be used to run on a new example? Here are some notes on the current state of the art. I assign each decompiler a score from 0 to 10 based on how easy it is to use the publicly available artifacts to run on a new example.
SLaDe: 2/10
SLaDe has a publicly released replication artifact but there are several problems that prevent it from being used on new examples:
- The models are trained on assembly code produced from compilers rather than disassemblers. This is probably minor.
- More problematically, SLaDe uses IO testcases during beam search to help detect the best candidate. It can be used without these, but the results will be worse. SLaDe does not contain a mechanism for producing testcases for new examples.
Below is a quote from a private conversation with the author:
You are right that IO are somehow used to select in the beam search, in the sense that we report pass@5. They are not strictly required to get the outputs though.
The link you sent is for the program synthesis dataset. In this one, IO generation was programmatic but still kind of manual, I don't think it would be feasible to automatically generate the props file in the general case. For the Github functions, we have a separate repo that automatically generates IO tests, but those are randomly generated and the quality depends on each case. If I had to redo now, I would ask an LLM to generate unit tests! I can give you access to the private repo we used to automatically generate the IO examples for the general case if you wish, but now I'd do it with LLMs rather than randomly.
LLM4Decompile: 9/10
LLM4Decompile has published model files on HuggingFace that can easily be used to run on new examples. I created a few HuggingFace Spaces for testing.
resym: 2/10
resym has a publicly released replication artifact. Unfortunately, as of February 2025, the artifact is missing the "prolog-based inference system for struct layout recovery" which is the key contribution of the paper. Thus it is not possible to run resym on new examples.
DeGPT: 8/10
DeGPT has a publicly released GitHub repository. I'm largely going on memory, but I used it previously on new examples and it was relatively easy to use. I did have to file a few PRs though.
Powered with by Gatsby 5.0